sam firke dot com

Rare blog, rattlin’ blog

Category: Work

  • AI coding in October 2026: AI independently evaluating AI
    ,

    AI coding in October 2026: AI independently evaluating AI

    AI writing only impressed me once, the first time I tried ChatGPT and asked it to write a limerick. Guessing the next token is a neat trick but it doesn’t know what I want to say so it can’t say it for me.

    But its coding ability is another thing entirely. I’ve been using AI models to help me code since late 2024 (I started with Claude Sonnet 3.5 and OpenAI GPT-4o in GitHub Copilot). Every couple of months something has blown my mind, from either a new technological breakthrough (new model, new harness) or simply a new-to-me use case. This post is about the latter.

    Sometimes I tell a friend or coworker about the breakthrough; other times I just sit and stare at the computer, or go for a walk. This time I’ll try writing it. My purpose is two-fold:

    1. A diary that captures a moment in time. AI coding has changed so rapidly, and so completely since 2024, that maybe it’ll be nice to have an archaeological record of what will be olden times.
    2. To give non-coders who might read this a glimpse of what AI can do with programming these days.

    Today I’m writing about “evals,” short for evaluation of AI products. I have built a few chatbots for internal use at work. At their simplest, they let users search “what is the maximum sick time paid out upon retirement?” and the most relevant chunks of policy text are fed to an AI model to synthesize. I could say more about these chatbots but that’s for another post.

    When I built them, I tested out different models to see which should handle the task of synthesizing the answer. I pick from the choices on OpenRouter, which can route your call to any of hundreds of models. My testing was ad-hoc: I’d run the same query against different models and see what the cheapest model was that could give a good answer in a fast enough response. “Good answer” was just my gut opinion.

    This month Anthropic released Claude Haiku 5.5, which scored high on benchmarks and was 90% cheaper than it’s predecessor Haiku 4.5. I wondered, if I swapped in Haiku 5.5 for the models currently powering my AI services (mostly Gemini 3.6 Flash), would I save money and get a better result? I decided that instead of hand-evaluating it myself on a few questions, I would direct Claude Code to do some evaluation.

    My prompt was simple. I feel a little embarrassed sharing a prompt but I’m trying to provide a window into where these things are at, so:

    Read more: AI coding in October 2026: AI independently evaluating AI

    Our different RAG services in this repo use different LLMs. At first we did no evals, then some informal / ad hoc testing. Today I’m interested in Claude Haiku 5.5, which is on OpenRouter for cheap and might outperform some of the models we’re using. Maybe this is a good occasion to formalize a set of evals? I’m new to eval practices for LLM work, so let’s maybe ease in with a single service. I was thinking you, Opus in Claude Code, would come up with evaluation tasks, then run the existing model vs Haiku 5.5 and score them. Store the results somewhere findable for future such work. Maybe it could capture qualitative notes too, e.g., if the responses have some characteristic or quirk, or if the prompts need to change to improve performance? Start by evaluating which model that we currently used is best suited for replacement with Haiku 5.5, based on its performance, class, release date, and cost on OpenRouter. Haiku 5.5 is currently $0.10 input and $0.50 output.

    Based on that, Opus 5.5 did the following:

    • Identify which AI chatbot service’s LLM was the best candidate for replacement with Haiku 5.5
    • Pick 31 example user questions based on our logs of questions users actually asked
    • Write its own answers to those and create a key for for what each answer must or must not include along with a scoring rubric
    • Run those sample questions through the models of interest (Haiku 5.5 and Gemini Flash 3.6)
    • Assign reviewer subagents to grade those outputs, blind to which model was which, and to choose which model had the better response to each
    • Compute the average scores, response time, and cost (based on actual billing from OpenRouter), concluding that Haiku 5.5 beat the Gemini model at a quarter of the cost.

    This was already a stunning result. I responded with:

    Evaluate the prompt improvements and implement any that are actual improvements.

    Another mediocre instruction from me and it was off to the races again. Opus tweaked the prompt that accompanies the user’s question, then ran the sample questions through the models again, blind-grading the outputs and double-checking the graded results from the reviewer subagents. It found an overall improvement, but noted, “the concision tweak on lookups shows mixed results (trading completeness for clarity), so I’ll test a v3 that keeps action-critical details while trimming only irrelevant provisions, then grade it against v2.”

    It found that v3 was not an improvement. In the process of grading the v3 answers, it noticed some recurring defects in the answers, like the answers containing “the context you provided” – a confusing response from the LLM, given that the excerpts it was fed were search results that the user never sees. So Opus 5.5 created a v4 prompt that was a tweak of v2, ran it all one more time, and ended up with this:
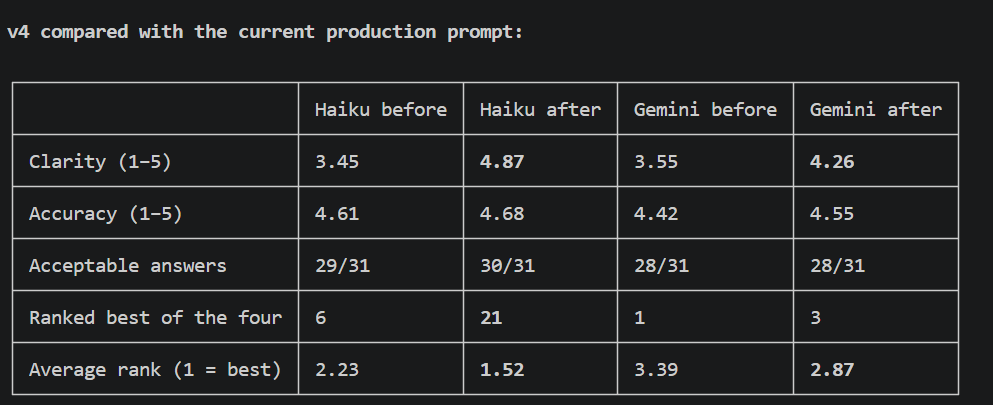
    a screenshot of Claude Code terminal output showing a grid comparing the scores of the different models and prompts on clarity, accuracy, acceptability, and ranked

    Along the way it found some bugs in the overall AI chatbot service: answers were sometimes cut off (I needed to increase the maximum allowed token limit for the OpenRouter response) and that one of my input policy documents was not being ingested correctly into the knowledge corpus, causing the LLM to be fed garbled text.

    The command /usage showed total cost $38.22, session runtime of 1h 10m. I used over 90% of my five-hour session limit, which I rarely hit. The main Opus agent context window was at 267k tokens (out of 1 million). I’ve just started using a Claude Code plugin called carbonlog to estimate the environmental damage caused by my personal Claude Code usage, but don’t have it installed on this work machine so can’t give a number here. Very much ballparking it, I’d wager 0.25-0.5 kg CO2 for a heavy Opus 5.5 session like this?

    I didn’t pay that $38.22. I’m on a Team plan that costs my employer $20/mo for a fixed amount of weekly usage. $38.22 is the cost I would have paid using the Claude API or on an Enterprise plan. Pretty good deal for a single session!

    But even $38 feels reasonable. This was an astounding session. I spent two minutes telling it to figure out if I should switch models and improve the prompt and I got an answer that was many times more rigorous than anything I could have feasibly done, in a sliver of the time.

    I glanced briefly at the answer key it drew up, read its output in the Claude Code session, and deployed its changes. Like so many other coding things these days, what I know about evals now is the general concepts and that AI can perform them autonomously. Which feels like all I need to know to apply them in the future.

    Is this post surprising or interesting or intelligible to non-programmers reading this? I wonder how this will age. At any rate, here’s a record of a facet of programming with AI that, in October 2026, impressed me a great deal. It’s a wild time to be coding.
    No comments on AI coding in October 2026: AI independently evaluating AI
  • ,

    Running Our Own Fork of Apache Superset in Production

    Here’s an update on my journey deploying Apache Superset and using Docker. It felt good to write about what I’ve learned at work, and it’s been a while: I don’t think I posted here that my job title is now Senior Data Engineer! But people who don’t work on computer infrastructure might not find this one interesting.

    In 2023, we deployed Apache Superset at the City of Ann Arbor as our Business Intelligence (BI) / data visualization platform, choosing it over Microsoft Power BI or Metabase. That decision has been a resounding success. Superset is a rock-solid product that keeps getting better … and* we’ve saved over $150k and counting in license costs vs. proprietary software.

    I’ve re-read the 2015 talk “Choose Boring Technology” a couple of times while working in my current job (that link goes to a slideshow version of the talk, turned into a website – that’s the format I’ve experienced it in). The author talks about having only three innovation tokens to spend on new tech at a given time. The rest has to be boring. Then when you’ve mastered the new tech, you get a token back to spend on something else.

    Deploying Superset took all my tokens: Docker, DevOps, Linux sysadmin. I said, we will only deploy official Docker images released by the Superset project. No way are we in the business of creating our own, this is complicated enough.

    I learned a ton in the intervening years. I’m still learning a ton. It’s great! As I’ve gotten those tokens back by becoming competent at those technologies, I’ve been able to do more with our Superset deployment.

    First that looked like building our own Superset Docker image, tweaking the environment but not touching the code. The project forced our hand on this because starting in 4.1.0, it no longer included basic drivers needed to use Superset out of the box, most notably the one to connect to the PostgreSQL backend database. I’m still not entirely convinced this was the right choice for the project but I saw the other side’s argument that everyone really ought to be building their own image.

    (more…)
    No comments on Running Our Own Fork of Apache Superset in Production
  • , ,

    Reblog: good takes on writing with LLMs

    I read these two pieces a few weeks ago and they were still kicking around in my head so I re-found them to share. They are nice complements to my 2023 post about LLMs being good coders and useless writers. They argue that, in fact, LLM writing is often worse than useless.

    Link 1: Using LLMs at Oxide. This is the best guide I’ve seen for expectations related to LLM usage at a particular workplace. It acknowledges LLMs as valuable tools while focusing on their ultimate purpose, serving humans. It’s good throughout, but the can’t-miss section is 2.4, LLMs as Writers. Here’s an excerpt:

    To those who can recognize an LLM’s reveals (an expanding demographic!), it’s just embarrassing — it’s as if the writer is walking around with their intellectual fly open. But there are deeper problems: LLM-generated writing undermines the authenticity of not just one’s writing but of the thinking behind it as well. If the prose is automatically generated, might the ideas be too? The reader can’t be sure — and increasingly, the hallmarks of LLM generation cause readers to turn off (or worse).

    Finally, LLM-generated prose undermines a social contract of sorts: absent LLMs, it is presumed that of the reader and the writer, it is the writer that has undertaken the greater intellectual exertion. (That is, it is more work to write than to read!) For the reader, this is important: should they struggle with an idea, they can reasonably assume that the writer themselves understands it — and it is the least a reader can do to labor to make sense of it.

    If, however, prose is LLM-generated, this social contract becomes ripped up: a reader cannot assume that the writer understands their ideas because they might not so much have read the product of the LLM that they tasked to write it. If one is lucky, these are LLM hallucinations: obviously wrong and quickly discarded. If one is unlucky, however, it will be a kind of LLM-induced cognitive dissonance: a puzzle in which pieces don’t fit because there is in fact no puzzle at all. This can leave a reader frustrated: why should they spend more time reading prose than the writer spent writing it?

    Link 2: Your Intellectual Fly Is Open, linked in the above quote. It’s a short post. My favorite chunk:

    When you use an LLM to author a [LinkedIn] post, you may think you are generating plausible writing, but you aren’t: to anyone who has seen even a modicum of LLM-generated content (a rapidly expanding demographic!), the LLM tells are impossible to ignore. Bluntly, your intellectual fly is open: lots of people notice — but no one is pointing it out. And the problem isn’t merely embarrassment: when you — person whose perspective I want to hear! — are obviously using an LLM to write posts for you, I don’t know what’s real and what is in fact generated fanfic. You definitely don’t sound like you, so…​ is the actual content real? I mean, maybe? But also maybe not. Regardless, I stop reading — and so do lots of others.

    I see this from a few people in my professional network. It’s brutal.

    “Your intellectual fly is open” is a good comparison to say “we see something embarrassing, we’re just not saying it” but it’s not strong enough in terms of the impact. Once I see someone I know writing through AI without disclosing it, I permanently distrust what they say from then on.

    I was prompted to write this post when at a friend’s recommendation I listened to a podcast episode, AI and I: Why Opus 4.5 Just Became the Most Influential AI Model. The episode was okay, and I didn’t like the second episode of that show I tried. But I was struck by something the guest, Paul Ford, said. He spends much of the show discussing how he uses LLMs all day for coding and research. He’s building an AI-based product. But when it comes to writing, he said the bottom-line limitation of using AI is simple: “it’s not me*.”

    It’s 2026 and I stand by my 2023 take. I double down on it, in fact: current LLM coding tools are leaps and bounds better than they were in 2023. When I wrote that post, Claude 3 had not yet been released, to say nothing of Claude Code, Github Copilot, Agent mode, etc.

    But generating code is writing for machines. And LLMs still aren’t useful for writing to humans.

    *I’m quoting that line from memory. I’m not going to re-listen to fact-check myself but please correct me if I got it wrong.

    2 comments on Reblog: good takes on writing with LLMs
  • , , ,

    LLMs are good coders, useless writers

    My writer friends say Large Language Models (LLMs) like ChatGPT and Bard are overhyped and useless. Software developer friends say they’re a valuable tool, so much so that some pay out-of-pocket for ChatGPT Plus. They’re both correct: the writing they spew is pointless at best, pernicious at worst. … and coding with them has become an exciting part of my job as a data analyst.

    Here I share a few concrete examples where they’ve shined for me at work and ruminate on why they’re good at coding but of limited use in writing. Compared to the general public, computer programmers are much more convinced of the potential of so-called Generative AI models. Perhaps these examples will help explain that difference.

    Example 1: Finding a typo in my code

    I was getting a generic error message from running this command, something whose Google results were not helpful. My prompt to Bard:

    Bard told me I had a “significant issue”:

    Yep! So trivial, but I wasn’t seeing it. It also suggested a styling change and, conveniently, gave me back the fixed code so that I could copy-paste it instead of correcting my typos. Here the LLM was able to work with my unique situation when StackOverflow and web searches were not helping. I like that the LLM can audit my code.

    Example 2: Writing a SQL query

    Today I started writing a query to check an assumption about my data. I could see that in translating my thoughts directly to code, I was getting long-winded, already on my third CTE (common table expression). There had to be a simpler way. I described my problem to Bard and it delivered.

    My prompt:

    Bard replied:

    (more…)
    5 comments on LLMs are good coders, useless writers
  • ,

    Stumbling blocks with Azure CLI on the AzureUSGovernment Cloud

    This is foremost a note to my future self, a reference for the next time I get stuck. If someone else finds it via a search engine, bonus!

    Using the Azure CLI (command line interface) on Microsoft’s Azure Government cloud is mostly like using their regular, non-gov cloud. Cloud computing on Azure has been a positive experience for me overall. But I’ve gotten burned a few times when the gov cloud operation needs a different command than what’s shown in the official Azure CLI docs.

    Each case took me several unhappy hours to figure out. The reason I was seeing a certain error message was unrelated to the reasons other people on the internet were served the same message. No one on StackOverflow asks, “might you be using the Azure gov cloud?”

    (more…)
    No comments on Stumbling blocks with Azure CLI on the AzureUSGovernment Cloud
  • , , , ,

    Same Developer, New Stack

    I’ve been fortunate to work with and on open-source software this year. That has been the case for most of a decade: I began using R in 2014. I hit a few milestones this summer that got me thinking about my OSS journey.

    I became a committer on the Apache Superset project. I’ve written previously about deploying Superset at work as the City of Ann Arbor’s data visualization platform. The codebase (Python and JavaScript) was totally new to me but I’ve been active in the community and helped update documentation.

    Those contributions were sufficient to get me voted in as a committer on the project. It’s a nice recognition and vote of confidence but more importantly gives me tools to have a greater impact. And I’m taking baby steps toward learning Superset’s backend. Yesterday I made my first contribution to the codebase, fixing a small bug just in time for the next major release.

    Superset has great momentum and a pleasant and involved (and growing!) community. It’s a great piece of software to use daily and I look forward to being a part of the project for the foreseeable future.

    I used pyjanitor for the first time today. I had known of pyjanitor‘s existence for years but only from afar. It started off as a Python port of my janitor R package, then grew to encompass other functionality. My janitor is written for beginners, and that came full circle today as I, a true Python beginner, used pyjanitor to wrangle some data. That was satisfying, though I’m such a Python rookie that I struggled to import the dang package.

    (more…)
    No comments on Same Developer, New Stack
  • , ,

    Coworking spaces aren’t profitable

    I gave a tour of Workantile this week to a prospective new member who shared her experience working out of The Wing’s DC branch. We got to talking about how WeWork and The Wing were valued in the billions and hundreds of millions of dollars, respectively, before crashing to nothing. Those valuations were clearly absurd, but as a coworking insider, I’ll go a step farther and say there’s not much money in operating a coworking space.

    That doesn’t mean coworking spaces aren’t valuable. Workantile has grown friendships, mentorships, careers, side projects, community services and made its members significantly happier. We kick around ideas, eat together, share recommendations and hand-me-downs. A long-time member swears that Workantile saved her marriage. But those benefits accrue to members and their networks and can’t easily be monetized by the space.

    And it doesn’t mean people shouldn’t create coworking spaces. On the contrary, now’s a perfect time. Office rents are down, the boom of newly-remote workers are getting lonely, and concern about COVID transmission is receding. But don’t launch a coworking space – or invest in someone else’s – thinking you’ll get rich. The numbers don’t work.

    (more…)
    1 comment on Coworking spaces aren’t profitable
  • , , ,

    Making the Switch to Apache Superset

    This is the story of how the City of Ann Arbor adopted Apache Superset as its business intelligence (BI) platform. Superset has been a superior product for both creators and consumers of our data dashboards and saves us 94% in costs compared to our prior solution.

    Background

    As the City of Ann Arbor’s data analyst, I spend a lot of time building charts and dashboards in our business intelligence / data visualization platform. When I started the job in 2021, we were halfway through a contract and I used that existing software as I completed my initial data reporting projects.

    After using it for a year, I was feeling its pain points. Building dashboards was a cumbersome and finicky process and my customers wanted more flexible and aesthetically-pleasing results. I began searching for something better.

    Being a government entity makes software procurement tricky – we can’t just shop and buy. Our prior BI platform was obtained via a long Request for Proposals (RFP) process. This time I wanted to try out products to make sure they would perform as expected. Will it work with our data warehouse? Can we embed charts in our public-facing webpages?

    The desire to try before buying led me to consider open-source options as well as products that we already had access to through existing contracts (i.e., Microsoft Power BI).

    (more…)
    5 comments on Making the Switch to Apache Superset
  • Reflections on five years of the janitor R package
    , , ,

    Reflections on five years of the janitor R package

    One thing led to another. In early 2016, I was participating in discussions on the #rstats Twitter hashtag, a community for users of the R programming language. There, Andrew Martin and I met and realized we were both R users working in K-12 education. That chance interaction led to me attending a meeting of education data users that April in NYC.

    Going through security at LaGuardia for my return flight, I chatted with Chris Haid about data science and R. Chris affirmed that I’d earned the right to call myself a “data scientist.” He also suggested that writing an R package wasn’t anything especially difficult.

    My plane home that night was hours late. Fired up and with unexpected free time on my hands, I took a few little helper functions I’d written for data cleaning in R and made my initial commits in assembling them into my first software package, janitor, following Hilary Parker’s how-to guide.

    That October, the janitor package was accepted to CRAN, the official public repository of R packages. I celebrated and set a goal of someday attaining 10,000 downloads.

    Yesterday janitor logged its one millionth download, wildly exceeding my expectations. I thought I’d take this occasion to crunch some usage numbers and write some reflections. This post is sort of a baby book for the project, almost five years in.

    By The Numbers

    This chart shows daily downloads since the package’s first CRAN release. The upper line (red) is weekdays, the lower line (green) is weekends. Each vertical line represents a new version published on CRAN.

    From the very beginning I was excited to have users, but this chart makes that exciting early usage seem miniscule. janitor’s most substantive updates were published in March 2018, April 2019, and April 2020, with it feeling more done each time, but most user adoption has occurred more recently than that. I guess I didn’t have to worry so much about breaking changes.

    Another way to look at the growth is year-over-year downloads:

    YearDownloadsRatio vs. Prior Year
    2016-1713,284–
    2017-1847,3043.56x
    2018-19161,4113.41x
    2019-20397,3902.46x
    2020-21 (~5 months)383,5956–
    Download counts are from the RStudio mirror, which does not represent all R user activity. That said, it’s the only available count and the standard measure of usage.
    (more…)
    1 comment on Reflections on five years of the janitor R package
  • , ,

    That feeling when your first user opens an issue

    You know how new businesses frame the first dollar they earn?

    I wrote an R package that interfaces with the SurveyMonkey API. I worked hard on it, on and off the clock, and it has a few subtle features of which I’m quite proud. It’s paying off, as my colleagues at TNTP have been using it to fetch and analyze their survey results.

    The company and I open-sourced the project, deciding that if we have already invested the work, others might as well benefit. And maybe some indirect benefits will accrue to the company as a result. I made the package repository public, advertised it in a few places, then waited. Like a new store opening its doors and waiting for that first customer.

    They showed up on Friday! With the project’s first GitHub star and a bug report that was good enough for me to quickly patch the problem. Others may have already been quietly using the package, but this was the first confirmed proof of use. It’s a great feeling as an open-source developer wondering, “I built it: will they come?”

    Consider this blog post to be me framing that dollar.

    No comments on That feeling when your first user opens an issue