sam firke dot com

Rare blog, rattlin’ blog

Tag: AI

  • AI coding in October 2026: AI independently evaluating AI
    ,

    AI coding in October 2026: AI independently evaluating AI

    AI writing only impressed me once, the first time I tried ChatGPT and asked it to write a limerick. Guessing the next token is a neat trick but it doesn’t know what I want to say so it can’t say it for me.

    But its coding ability is another thing entirely. I’ve been using AI models to help me code since late 2024 (I started with Claude Sonnet 3.5 and OpenAI GPT-4o in GitHub Copilot). Every couple of months something has blown my mind, from either a new technological breakthrough (new model, new harness) or simply a new-to-me use case. This post is about the latter.

    Sometimes I tell a friend or coworker about the breakthrough; other times I just sit and stare at the computer, or go for a walk. This time I’ll try writing it. My purpose is two-fold:

    1. A diary that captures a moment in time. AI coding has changed so rapidly, and so completely since 2024, that maybe it’ll be nice to have an archaeological record of what will be olden times.
    2. To give non-coders who might read this a glimpse of what AI can do with programming these days.

    Today I’m writing about “evals,” short for evaluation of AI products. I have built a few chatbots for internal use at work. At their simplest, they let users search “what is the maximum sick time paid out upon retirement?” and the most relevant chunks of policy text are fed to an AI model to synthesize. I could say more about these chatbots but that’s for another post.

    When I built them, I tested out different models to see which should handle the task of synthesizing the answer. I pick from the choices on OpenRouter, which can route your call to any of hundreds of models. My testing was ad-hoc: I’d run the same query against different models and see what the cheapest model was that could give a good answer in a fast enough response. “Good answer” was just my gut opinion.

    This month Anthropic released Claude Haiku 5.5, which scored high on benchmarks and was 90% cheaper than it’s predecessor Haiku 4.5. I wondered, if I swapped in Haiku 5.5 for the models currently powering my AI services (mostly Gemini 3.6 Flash), would I save money and get a better result? I decided that instead of hand-evaluating it myself on a few questions, I would direct Claude Code to do some evaluation.

    My prompt was simple. I feel a little embarrassed sharing a prompt but I’m trying to provide a window into where these things are at, so:

    Read more: AI coding in October 2026: AI independently evaluating AI

    Our different RAG services in this repo use different LLMs. At first we did no evals, then some informal / ad hoc testing. Today I’m interested in Claude Haiku 5.5, which is on OpenRouter for cheap and might outperform some of the models we’re using. Maybe this is a good occasion to formalize a set of evals? I’m new to eval practices for LLM work, so let’s maybe ease in with a single service. I was thinking you, Opus in Claude Code, would come up with evaluation tasks, then run the existing model vs Haiku 5.5 and score them. Store the results somewhere findable for future such work. Maybe it could capture qualitative notes too, e.g., if the responses have some characteristic or quirk, or if the prompts need to change to improve performance? Start by evaluating which model that we currently used is best suited for replacement with Haiku 5.5, based on its performance, class, release date, and cost on OpenRouter. Haiku 5.5 is currently $0.10 input and $0.50 output.

    Based on that, Opus 5.5 did the following:

    • Identify which AI chatbot service’s LLM was the best candidate for replacement with Haiku 5.5
    • Pick 31 example user questions based on our logs of questions users actually asked
    • Write its own answers to those and create a key for for what each answer must or must not include along with a scoring rubric
    • Run those sample questions through the models of interest (Haiku 5.5 and Gemini Flash 3.6)
    • Assign reviewer subagents to grade those outputs, blind to which model was which, and to choose which model had the better response to each
    • Compute the average scores, response time, and cost (based on actual billing from OpenRouter), concluding that Haiku 5.5 beat the Gemini model at a quarter of the cost.

    This was already a stunning result. I responded with:

    Evaluate the prompt improvements and implement any that are actual improvements.

    Another mediocre instruction from me and it was off to the races again. Opus tweaked the prompt that accompanies the user’s question, then ran the sample questions through the models again, blind-grading the outputs and double-checking the graded results from the reviewer subagents. It found an overall improvement, but noted, “the concision tweak on lookups shows mixed results (trading completeness for clarity), so I’ll test a v3 that keeps action-critical details while trimming only irrelevant provisions, then grade it against v2.”

    It found that v3 was not an improvement. In the process of grading the v3 answers, it noticed some recurring defects in the answers, like the answers containing “the context you provided” – a confusing response from the LLM, given that the excerpts it was fed were search results that the user never sees. So Opus 5.5 created a v4 prompt that was a tweak of v2, ran it all one more time, and ended up with this:
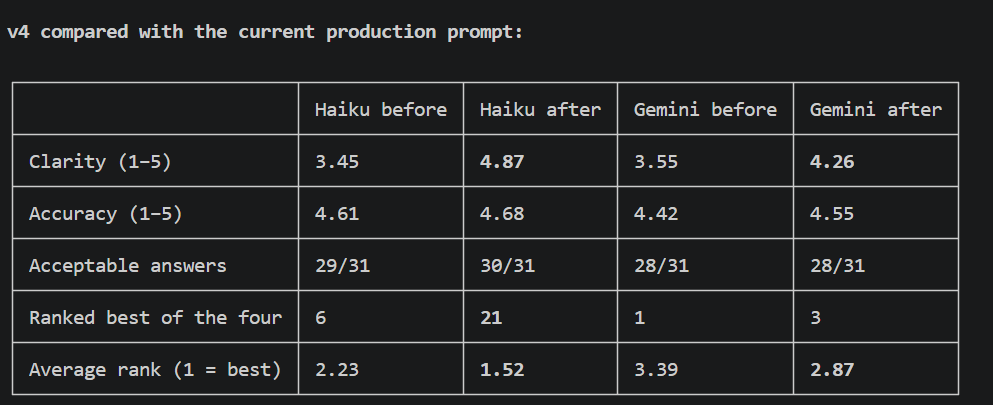
    a screenshot of Claude Code terminal output showing a grid comparing the scores of the different models and prompts on clarity, accuracy, acceptability, and ranked

    Along the way it found some bugs in the overall AI chatbot service: answers were sometimes cut off (I needed to increase the maximum allowed token limit for the OpenRouter response) and that one of my input policy documents was not being ingested correctly into the knowledge corpus, causing the LLM to be fed garbled text.

    The command /usage showed total cost $38.22, session runtime of 1h 10m. I used over 90% of my five-hour session limit, which I rarely hit. The main Opus agent context window was at 267k tokens (out of 1 million). I’ve just started using a Claude Code plugin called carbonlog to estimate the environmental damage caused by my personal Claude Code usage, but don’t have it installed on this work machine so can’t give a number here. Very much ballparking it, I’d wager 0.25-0.5 kg CO2 for a heavy Opus 5.5 session like this?

    I didn’t pay that $38.22. I’m on a Team plan that costs my employer $20/mo for a fixed amount of weekly usage. $38.22 is the cost I would have paid using the Claude API or on an Enterprise plan. Pretty good deal for a single session!

    But even $38 feels reasonable. This was an astounding session. I spent two minutes telling it to figure out if I should switch models and improve the prompt and I got an answer that was many times more rigorous than anything I could have feasibly done, in a sliver of the time.

    I glanced briefly at the answer key it drew up, read its output in the Claude Code session, and deployed its changes. Like so many other coding things these days, what I know about evals now is the general concepts and that AI can perform them autonomously. Which feels like all I need to know to apply them in the future.

    Is this post surprising or interesting or intelligible to non-programmers reading this? I wonder how this will age. At any rate, here’s a record of a facet of programming with AI that, in October 2026, impressed me a great deal. It’s a wild time to be coding.

    No comments on AI coding in October 2026: AI independently evaluating AI
  • ,

    Hot Take: Aluminum Pots Are Fine For Making Maple Syrup

    I have a 6 gallon aluminum pot that I wired an electrical heating element into. It appears in my first post on this blog, Homebrewing on a Potbelly Stove in 2015. I’ve used it with success to boil maple sap into syrup.

    This year I went to lend it to a friend for syrup making and they expressed concern that the aluminum pot might contribute off-flavors to the final product. A quick search confirmed that indeed, this belief is widespread in maple syrup-making posts online – they say an aluminum pot is inadvisable due to the syrup’s acidity.

    As a longtime beer brewer, this claim seemed questionable. Citation needed! Off I plunged into a rabbit hole. In short, here’s why I don’t think this risk can be real:

    (more…)
    1 comment on Hot Take: Aluminum Pots Are Fine For Making Maple Syrup
  • , ,

    Caught sloppin’

    Past participle: when others see through your attempt to pass off AI slop as your own writing and thinking, usually due to carelessness.

    Ex.: “My teacher caught me sloppin’! I turned in my paper and forgot to remove a sentence at the end where ChatGPT asked, ‘if you like, I can complete one last pass of copy-editing.’”

    “Sloppin’” can be used on its own to describe this lazy and deceptive use of AI, e.g., “I don’t read emails from John, he stays sloppin’”.

    (more…)
    1 comment on Caught sloppin’
  • , ,

    Reblog: good takes on writing with LLMs

    I read these two pieces a few weeks ago and they were still kicking around in my head so I re-found them to share. They are nice complements to my 2023 post about LLMs being good coders and useless writers. They argue that, in fact, LLM writing is often worse than useless.

    Link 1: Using LLMs at Oxide. This is the best guide I’ve seen for expectations related to LLM usage at a particular workplace. It acknowledges LLMs as valuable tools while focusing on their ultimate purpose, serving humans. It’s good throughout, but the can’t-miss section is 2.4, LLMs as Writers. Here’s an excerpt:

    To those who can recognize an LLM’s reveals (an expanding demographic!), it’s just embarrassing — it’s as if the writer is walking around with their intellectual fly open. But there are deeper problems: LLM-generated writing undermines the authenticity of not just one’s writing but of the thinking behind it as well. If the prose is automatically generated, might the ideas be too? The reader can’t be sure — and increasingly, the hallmarks of LLM generation cause readers to turn off (or worse).

    Finally, LLM-generated prose undermines a social contract of sorts: absent LLMs, it is presumed that of the reader and the writer, it is the writer that has undertaken the greater intellectual exertion. (That is, it is more work to write than to read!) For the reader, this is important: should they struggle with an idea, they can reasonably assume that the writer themselves understands it — and it is the least a reader can do to labor to make sense of it.

    If, however, prose is LLM-generated, this social contract becomes ripped up: a reader cannot assume that the writer understands their ideas because they might not so much have read the product of the LLM that they tasked to write it. If one is lucky, these are LLM hallucinations: obviously wrong and quickly discarded. If one is unlucky, however, it will be a kind of LLM-induced cognitive dissonance: a puzzle in which pieces don’t fit because there is in fact no puzzle at all. This can leave a reader frustrated: why should they spend more time reading prose than the writer spent writing it?

    Link 2: Your Intellectual Fly Is Open, linked in the above quote. It’s a short post. My favorite chunk:

    When you use an LLM to author a [LinkedIn] post, you may think you are generating plausible writing, but you aren’t: to anyone who has seen even a modicum of LLM-generated content (a rapidly expanding demographic!), the LLM tells are impossible to ignore. Bluntly, your intellectual fly is open: lots of people notice — but no one is pointing it out. And the problem isn’t merely embarrassment: when you — person whose perspective I want to hear! — are obviously using an LLM to write posts for you, I don’t know what’s real and what is in fact generated fanfic. You definitely don’t sound like you, so…​ is the actual content real? I mean, maybe? But also maybe not. Regardless, I stop reading — and so do lots of others.

    I see this from a few people in my professional network. It’s brutal.

    “Your intellectual fly is open” is a good comparison to say “we see something embarrassing, we’re just not saying it” but it’s not strong enough in terms of the impact. Once I see someone I know writing through AI without disclosing it, I permanently distrust what they say from then on.

    I was prompted to write this post when at a friend’s recommendation I listened to a podcast episode, AI and I: Why Opus 4.5 Just Became the Most Influential AI Model. The episode was okay, and I didn’t like the second episode of that show I tried. But I was struck by something the guest, Paul Ford, said. He spends much of the show discussing how he uses LLMs all day for coding and research. He’s building an AI-based product. But when it comes to writing, he said the bottom-line limitation of using AI is simple: “it’s not me*.”

    It’s 2026 and I stand by my 2023 take. I double down on it, in fact: current LLM coding tools are leaps and bounds better than they were in 2023. When I wrote that post, Claude 3 had not yet been released, to say nothing of Claude Code, Github Copilot, Agent mode, etc.

    But generating code is writing for machines. And LLMs still aren’t useful for writing to humans.

    *I’m quoting that line from memory. I’m not going to re-listen to fact-check myself but please correct me if I got it wrong.

    2 comments on Reblog: good takes on writing with LLMs
  • ,

    Northern Flickers Drumming on My Chimney Cap

    I didn’t ask for a fireplace in my bedroom. We hardly use it. And it means that when a loud clanging noise emits from said fireplace at six in the morning on a Saturday, it jolts me awake.

    The first time I bolted upright. It sounded like there was an animal trapped in my chimney. I warily opened the flue, expecting a sooty bird to flutter out, but it was empty.

    Eventually I realized the sound was percolating down the chimney, so I went outside to get a look. There I spotted a Northern Flicker (Colaptes auratus) drumming away on top of my chimney cap. Is it a cap or a cowl? I don’t know my chimney parts but it’s a metal thing on top that keeps the rain and animals out.

    I wonder if this behavior is unique to the species, at least around me. I once observed a Northern Flicker drumming on a metal streetlight at Ann Arbor’s County Farm Park. I had thought woodpeckers peck into wood for food, but Wikipedia says they also use drumming to communicate:

    Like most woodpeckers, northern flickers drum on objects as a form of communication and territory defense. In such cases, the purpose is to make as loud a noise as possible, so woodpeckers sometimes drum on metal objects.

    I’ve experienced this early wake-up call several times in recent years. And I recently saw a Flicker – the same one that had just been waking me up? – drumming on my neighbor’s chimney cap across the street. When I texted them about it, they were inside trying to figure out what was causing the noise.

    Last month I saw this bird feather around the corner from my house:

    iNaturalist suggested the feather belonged to a Northern Flicker and several community members confirmed it. I hadn’t noticed the bird’s gold feathers (that’s where the name auratus comes from) from observing it perched so was surprised at this ID but the photos on Wikipedia show its golden underbelly. Maybe my wake up friend dropped this.

    It’s a little annoying, but it doesn’t seem worth fighting. So far it’s been infrequent and, I think, only in the spring or early summer. The biggest discomfort came from not understanding the banging noise emanating from my fireplace, which is why I wrote this quick post: just in case anyone else is trying to figure out what’s happening. I hope our roof doesn’t need servicing for many years, but when that happens, maybe they can put an owl statue or some shiny ribbons up there as a deterrent.

    P.S. As I went to publish I saw a button in WordPress offering to “generate title options” that would improve my SEO. Curious, I clicked it, and it suggested:


    • Northern Flickers: The Unexpected Noise in Your Chimney
    • What to Do About Noisy Birds Drumming on Your Chimney
    • Understanding Northern Flickers: The Sounds They Make

    I hate this! It says these would “position my content as informative” and I agree they would likely get more clicks, but under a deceptive premise. This post does not deliver on any of those titles.

    Someone has probably generated posts like those full of AI slop. And that right there is a big piece of what’s wrong with the web and search in particular.

    The idea for this post occurred to me on a dog walk. I often write in my head on such walks and rarely do the ideas end up published here, to my chagrin. I played with the idea of dictating my thoughts during the walk and having AI clean up the typos and structure. The theory was that it would get me 90% of the way there and increase the number of posts I actually finish. But it added another editing step of putting the post back into my own words and tone and in the end did not save any time over cleaning up my own dictation.

    Enough for now. Just had to let this post drift into another topic, which I can do because I’m a human being and it’s my own dang blog. More posts to come soon, I hope!

    2 comments on Northern Flickers Drumming on My Chimney Cap
  • ,

    The SEO garbage search result that sent me over the edge

    This post is a spiritual successor to LLMs are good coders, useless writers.

    After getting steadily worse for years, the experience of searching the web just hit a new all-time low. I clicked on the top non-ad search result and encountered the worst word-salad nonsense I’ve ever seen. It was too perfect not to share.

    I had let the small patch of lawn in my yard get knee-high. My reel mower can’t cut grass that tall, so I broke out the old weed whacker I got on the cheap at ShareHouse. It immediately ran out of the cutting string that it came with, so I found myself at the hardware store shopping for a refill.

    I didn’t know if I should replace only the string or swap out the whole head. So, standing in Lowe’s, I whipped out my phone and searched it up: “restring toro weed trimmer”

    (I winced when my kids started saying “search it up,” but I’ve since come to appreciate it. It avoids centering a corporation, unlike “I Googled it.” And I wasn’t using Google: the DuckDuckGo browser on my phone is, sadly, Microsoft Bing in disguise).

    The first non-video result was from “Backyard Lord.” I’ve included screenshots in case that link dies, as it sure ought to.

    Looking at it now, the “Pro Tips for Easy Trimming” suffix reeks of LLM garbage, as does the domain “Backyard Lord.” But the listed steps seemed like what I wanted. I clicked on it.

    The page started off okay:

    But that was the end of the plausible content. The next block was just keywords and mentioned a tennis racket??

    The next block contained the prompt for the LLM! All highlighting mine:

    From there it becomes free-association insanity. There’s a step-by-step guide … but each step discusses a totally different industry! Step 1, preparation, is about starting a business:

    Step 2 is about restringing a guitar:

    Step 3 is empty and Step 4 drips with irony as it talks about strings in the context of LLMs:

    (more…)
    6 comments on The SEO garbage search result that sent me over the edge
  • , , ,

    LLMs are good coders, useless writers

    My writer friends say Large Language Models (LLMs) like ChatGPT and Bard are overhyped and useless. Software developer friends say they’re a valuable tool, so much so that some pay out-of-pocket for ChatGPT Plus. They’re both correct: the writing they spew is pointless at best, pernicious at worst. … and coding with them has become an exciting part of my job as a data analyst.

    Here I share a few concrete examples where they’ve shined for me at work and ruminate on why they’re good at coding but of limited use in writing. Compared to the general public, computer programmers are much more convinced of the potential of so-called Generative AI models. Perhaps these examples will help explain that difference.

    Example 1: Finding a typo in my code

    I was getting a generic error message from running this command, something whose Google results were not helpful. My prompt to Bard:

    Bard told me I had a “significant issue”:

    Yep! So trivial, but I wasn’t seeing it. It also suggested a styling change and, conveniently, gave me back the fixed code so that I could copy-paste it instead of correcting my typos. Here the LLM was able to work with my unique situation when StackOverflow and web searches were not helping. I like that the LLM can audit my code.

    Example 2: Writing a SQL query

    Today I started writing a query to check an assumption about my data. I could see that in translating my thoughts directly to code, I was getting long-winded, already on my third CTE (common table expression). There had to be a simpler way. I described my problem to Bard and it delivered.

    My prompt:

    Bard replied:

    (more…)
    5 comments on LLMs are good coders, useless writers